Bookmark referencing Hopper, a travel app, shared by Oskar Groth. ↗
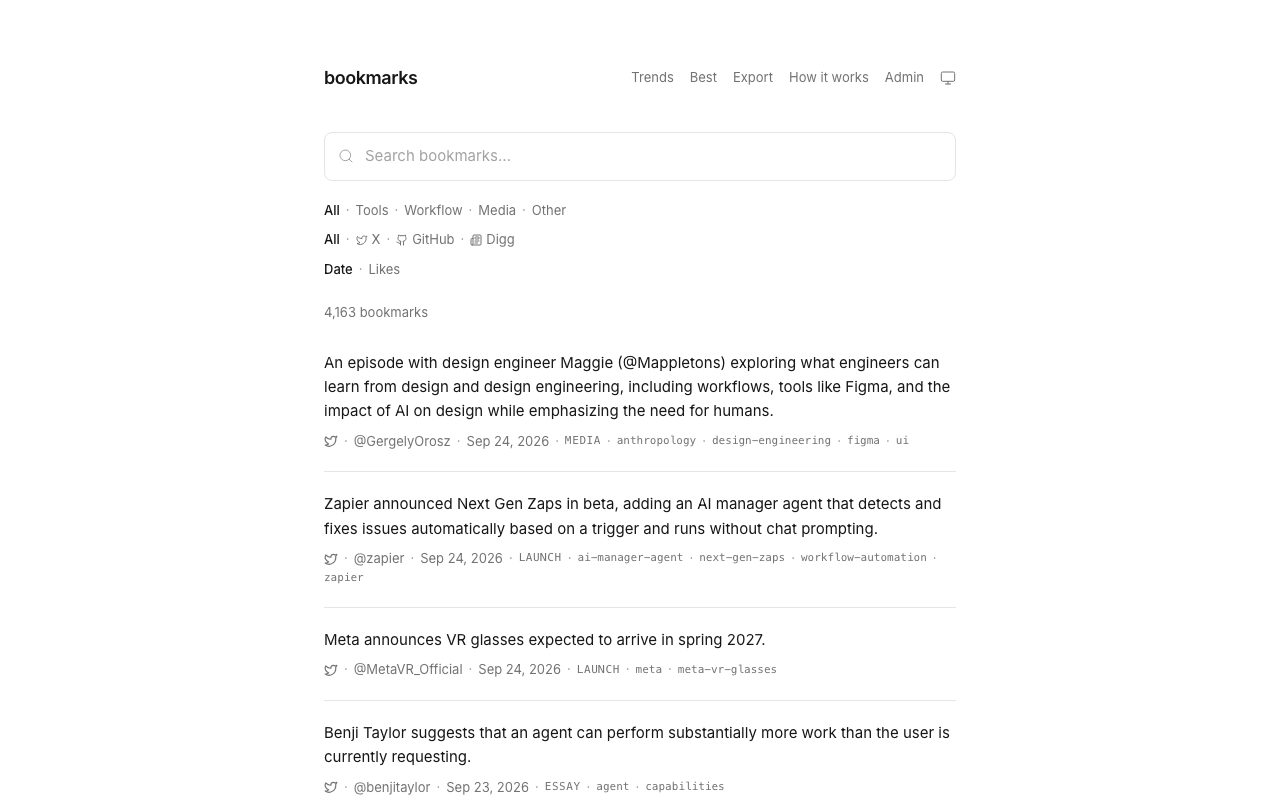
Bookmarks
I rely on X bookmarks for nearly all the content in the newsletter, plus a bunch of stuff I want to try, use or copy later. But it’s impossible to search them. So I built a site that can, and my agents search it too.
Where it started
That morning I had my agent on the Mac Mini write specs for four ideas. This was one of them. 1,147 lines:
spec/SPEC.md
# Bookmarks DB — Product Spec
> Ben's Twitter/X bookmarks as a searchable public database.
## Overview
Ben (@bentossell) has thousands of Twitter/X bookmarks — tools, projects, builders, opinions, tutorials. This project ingests them into a Supabase database, enriches each with LLM-generated metadata (categories, tags, product names), and serves them through a fast public search UI.
**Goal:** A public website where anyone can search/filter Ben's curated bookmarks. Think "Product Hunt meets bookmarks" — a discovery tool for the AI/tech ecosystem.
**URL target:** `bookmarks.bentossell.com` or `bookmarks.bensbites.com`
---
## Architecture
```
┌─────────────┐ ┌──────────────┐ ┌───────────┐ ┌──────────┐
│ bird CLI │────▶│ Ingestion │────▶│ Supabase │────▶│ Next.js │
│ (bookmarks) │ │ Pipeline │ │ Postgres │ │ Web UI │
└─────────────┘ └──────┬───────┘ └─────┬─────┘ └──────────┘
│ │
┌──────▼───────┐ ┌─────▼─────┐
│ Enrichment │ │ Vector │
│ (LLM batch) │ │ Search │
└──────────────┘ └───────────┘
```
**Stack:**
- **Runtime:** Bun + TypeScript
- **Database:** Supabase (Postgres + pgvector + full-text search)
- **Web UI:** Next.js 15 (App Router) + Tailwind + shadcn/ui
- **Hosting:** Vercel
- **LLM:** OpenAI gpt-4.1-mini for enrichment, text-embedding-3-small for vectors
- **Sync:** Launchd cron (Mac Mini) or Vercel Cron
---
## Data Model
### Source Data (from `bird bookmarks --json`)
Each bookmark from the bird CLI provides:
```typescript
interface RawBookmark {
id: string // tweet ID
text: string // tweet text (full)
createdAt: string // "Thu Mar 19 16:22:54 +0000 2026"
replyCount: number
retweetCount: number
likeCount: number
conversationId: string
inReplyToStatusId?: string
author: {
username: string // handle without @
name: string // display name
}
authorId: string
}
```
With `--json-full`, additional fields from `_raw`:
- `_raw.legacy.bookmark_count` — how many people bookmarked it
- `_raw.legacy.favorite_count` — likes
- `_raw.legacy.entities.urls[]` — expanded URLs
- `_raw.legacy.entities.hashtags[]`
- `_raw.legacy.entities.user_mentions[]`
- `_raw.views.count` — view count
- `_raw.legacy.quote_count`
- `_raw.legacy.lang`
### Supabase Schema
```sql
-- Enable extensions
create extension if not exists "vector";
create extension if not exists "pg_trgm";
-- Authors table
create table authors (
id text primary key, -- Twitter user ID
username text not null unique, -- handle
display_name text not null,
bio text,
profile_image_url text,
followers_count integer,
verified boolean default false,
created_at timestamptz default now(),
updated_at timestamptz default now()
);
create index idx_authors_username on authors (username);
-- Categories enum
create type bookmark_category as enum (
'tool',
'project',
'opinion',
'tutorial',
'news',
'thread',
'launch',
'resource',
'demo',
'hiring',
'funding',
'meme',
'other'
);
-- Main bookmarks table
create table bookmarks (
id text primary key, -- tweet ID
author_id text not null references authors(id),
text text not null, -- full tweet text
category bookmark_category default 'other',
url text not null, -- link to original tweet
tweet_created_at timestamptz not null, -- when tweet was posted
bookmarked_at timestamptz, -- when Ben bookmarked it (if available)
ingested_at timestamptz default now(), -- when we pulled it in
enriched_at timestamptz, -- when LLM enrichment ran
-- Engagement metrics
like_count integer default 0,
retweet_count integer default 0,
reply_count integer default 0,
quote_count integer default 0,
view_count integer default 0,
bookmark_count integer default 0, -- public bookmark count
-- Enrichment fields (LLM-generated)
summary text, -- 1-2 sentence summary
relevance_score smallint, -- 1-5 quality/relevance rating
is_thread boolean default false,
language text default 'en',
-- Conversation context
conversation_id text,
in_reply_to_id text,
-- Search vectors
search_vector tsvector, -- full-text search
embedding vector(1536), -- semantic search (text-embedding-3-small)
created_at timestamptz default now(),
updated_at timestamptz default now()
);
-- Full-text search index
create index idx_bookmarks_search on bookmarks using gin(search_vector);
-- Vector search index (IVFFlat for <10k rows, switch to HNSW at scale)
create index idx_bookmarks_embedding on bookmarks using ivfflat (embedding vector_cosine_ops) with (lists = 100);
-- Category + date indexes
create index idx_bookmarks_category on bookmarks (category);
create index idx_bookmarks_tweet_date on bookmarks (tweet_created_at desc);
create index idx_bookmarks_relevance on bookmarks (relevance_score desc);
create index idx_bookmarks_author on bookmarks (author_id);
-- Trigger to auto-update search_vector
create or replace function bookmarks_search_vector_update() returns trigger as $$
begin
new.search_vector :=
setweight(to_tsvector('english', coalesce(new.summary, '')), 'A') ||
setweight(to_tsvector('english', coalesce(new.text, '')), 'B');
new.updated_at := now();
return new;
end;
$$ language plpgsql;
create trigger trg_bookmarks_search_vector
before insert or update of text, summary on bookmarks
for each row execute function bookmarks_search_vector_update();
-- Tags table (many-to-many)
create table tags (
id serial primary key,
name text not null unique,
slug text not null unique,
count integer default 0 -- denormalized count for UI
);
create index idx_tags_slug on tags (slug);
create index idx_tags_count on tags (count desc);
create table bookmark_tags (
bookmark_id text references bookmarks(id) on delete cascade,
tag_id integer references tags(id) on delete cascade,
primary key (bookmark_id, tag_id)
);
create index idx_bookmark_tags_tag on bookmark_tags (tag_id);
-- Products/tools mentioned
create table products (
id serial primary key,
name text not null,
slug text not null unique,
url text, -- product URL
repo_url text, -- GitHub URL if applicable
description text,
count integer default 0 -- how many bookmarks mention it
);
create index idx_products_slug on products (slug);
create table bookmark_products (
bookmark_id text references bookmarks(id) on delete cascade,
product_id integer references products(id) on delete cascade,
primary key (bookmark_id, product_id)
);
-- URLs extracted from tweets
create table bookmark_urls (
id serial primary key,
bookmark_id text references bookmarks(id) on delete cascade,
display_url text,
expanded_url text not null,
title text, -- fetched page title (optional)
domain text
);
create index idx_bookmark_urls_bookmark on bookmark_urls (bookmark_id);
create index idx_bookmark_urls_domain on bookmark_urls (domain);
-- Sync state tracking
create table sync_state (
id serial primary key,
last_cursor text, -- bird CLI pagination cursor
last_sync_at timestamptz,
bookmarks_synced integer default 0,
bookmarks_enriched integer default 0,
status text default 'idle', -- idle | syncing | enriching | error
error_message text,
created_at timestamptz default now()
);
-- Row Level Security (public read, service write)
alter table bookmarks enable row level security;
alter table authors enable row level security;
alter table tags enable row level security;
alter table bookmark_tags enable row level security;
alter table products enable row level security;
alter table bookmark_products enable row level security;
alter table bookmark_urls enable row level security;
-- Public read policies
create policy "Public read bookmarks" on bookmarks for select using (true);
create policy "Public read authors" on authors for select using (true);
create policy "Public read tags" on tags for select using (true);
create policy "Public read bookmark_tags" on bookmark_tags for select using (true);
create policy "Public read products" on products for select using (true);
create policy "Public read bookmark_products" on bookmark_products for select using (true);
create policy "Public read bookmark_urls" on bookmark_urls for select using (true);
-- Service role write policies (for ingestion pipeline)
create policy "Service write bookmarks" on bookmarks for all using (true) with check (true);
create policy "Service write authors" on authors for all using (true) with check (true);
create policy "Service write tags" on tags for all using (true) with check (true);
create policy "Service write bookmark_tags" on bookmark_tags for all using (true) with check (true);
create policy "Service write products" on products for all using (true) with check (true);
create policy "Service write bookmark_products" on bookmark_products for all using (true) with check (true);
create policy "Service write bookmark_urls" on bookmark_urls for all using (true) with check (true);
```
### Supabase Database Functions
```sql
-- Full-text search function
create or replace function search_bookmarks(
query text,
category_filter bookmark_category default null,
tag_slugs text[] default null,
author_filter text default null,
date_from timestamptz default null,
date_to timestamptz default null,
sort_by text default 'relevance',
page_size integer default 20,
page_offset integer default 0
)
returns table (
id text,
text text,
summary text,
category bookmark_category,
url text,
tweet_created_at timestamptz,
like_count integer,
view_count integer,
relevance_score smallint,
author_username text,
author_display_name text,
author_profile_image text,
tags text[],
product_names text[],
rank real
)
language sql stable
as $$
select
b.id,
b.text,
b.summary,
b.category,
b.url,
b.tweet_created_at,
b.like_count,
b.view_count,
b.relevance_score,
a.username as author_username,
a.display_name as author_display_name,
a.profile_image_url as author_profile_image,
array(
select t.name from tags t
join bookmark_tags bt on bt.tag_id = t.id
where bt.bookmark_id = b.id
) as tags,
array(
select p.name from products p
join bookmark_products bp on bp.product_id = p.id
where bp.bookmark_id = b.id
) as product_names,
case
when query is not null and query != ''
then ts_rank(b.search_vector, websearch_to_tsquery('english', query))
else 0
end as rank
from bookmarks b
join authors a on a.id = b.author_id
where
(query is null or query = '' or b.search_vector @@ websearch_to_tsquery('english', query))
and (category_filter is null or b.category = category_filter)
and (author_filter is null or a.username = author_filter)
and (date_from is null or b.tweet_created_at >= date_from)
and (date_to is null or b.tweet_created_at <= date_to)
and (tag_slugs is null or exists (
select 1 from bookmark_tags bt
join tags t on t.id = bt.tag_id
where bt.bookmark_id = b.id and t.slug = any(tag_slugs)
))
order by
case when sort_by = 'relevance' and query is not null and query != ''
then ts_rank(b.search_vector, websearch_to_tsquery('english', query))
else 0
end desc,
case when sort_by = 'date' then extract(epoch from b.tweet_created_at) else 0 end desc,
case when sort_by = 'likes' then b.like_count else 0 end desc,
b.tweet_created_at desc
limit page_size
offset page_offset;
$$;
-- Semantic search function
create or replace function semantic_search_bookmarks(
query_embedding vector(1536),
match_threshold float default 0.7,
match_count integer default 20
)
returns table (
id text,
text text,
summary text,
category bookmark_category,
url text,
similarity float
)
language sql stable
as $$
select
b.id,
b.text,
b.summary,
b.category,
b.url,
1 - (b.embedding <=> query_embedding) as similarity
from bookmarks b
where 1 - (b.embedding <=> query_embedding) > match_threshold
order by b.embedding <=> query_embedding
limit match_count;
$$;
-- Stats function
create or replace function get_bookmark_stats()
returns json
language sql stable
as $$
select json_build_object(
'total_bookmarks', (select count(*) from bookmarks),
'total_enriched', (select count(*) from bookmarks where enriched_at is not null),
'total_authors', (select count(*) from authors),
'total_tags', (select count(*) from tags),
'total_products', (select count(*) from products),
'categories', (
select json_object_agg(category, cnt)
from (select category, count(*) as cnt from bookmarks group by category) sub
),
'top_tags', (
select json_agg(json_build_object('name', name, 'count', count) order by count desc)
from (select name, count from tags order by count desc limit 20) sub
),
'top_authors', (
select json_agg(json_build_object('username', username, 'count', cnt) order by cnt desc)
from (
select a.username, count(*) as cnt
from bookmarks b join authors a on a.id = b.author_id
group by a.username order by cnt desc limit 20
) sub
),
'date_range', json_build_object(
'oldest', (select min(tweet_created_at) from bookmarks),
'newest', (select max(tweet_created_at) from bookmarks)
)
);
$$;
```
---
## Ingestion Pipeline
### Phase 1: Pull bookmarks from bird CLI
```typescript
// src/ingest/pull.ts
interface PullOptions {
count?: number // specific count, or
all?: boolean // pull everything
maxPages?: number // limit pages for --all
cursor?: string // resume from cursor
}
async function pullBookmarks(opts: PullOptions): Promise<RawBookmark[]> {
// 1. Build bird CLI command
// bird bookmarks --json-full --all --max-pages N
// or bird bookmarks --json-full -n <count>
//
// 2. Parse JSON output
// 3. Return array of RawBookmark
//
// Rate limiting: bird CLI handles Twitter API pacing internally.
// For --all, expect ~20 bookmarks per page, ~1-2 sec per page.
}
```
### Phase 2: Transform & Load
```typescript
// src/ingest/transform.ts
function transformBookmark(raw: RawBookmarkFull): BookmarkInsert {
return {
id: raw.id,
author_id: raw.authorId,
text: raw.text,
url: `https://x.com/${raw.author.username}/status/${raw.id}`,
tweet_created_at: parseTwitterDate(raw.createdAt),
like_count: raw._raw?.legacy?.favorite_count ?? raw.likeCount,
retweet_count: raw.retweetCount,
reply_count: raw.replyCount,
quote_count: raw._raw?.legacy?.quote_count ?? 0,
view_count: parseInt(raw._raw?.views?.count ?? '0'),
bookmark_count: raw._raw?.legacy?.bookmark_count ?? 0,
conversation_id: raw.conversationId,
in_reply_to_id: raw.inReplyToStatusId ?? null,
language: raw._raw?.legacy?.lang ?? 'en',
}
}
function transformAuthor(raw: RawBookmarkFull): AuthorInsert {
const legacy = raw._raw?.core?.user_results?.result?.legacy
return {
id: raw.authorId,
username: raw.author.username,
display_name: raw.author.name,
bio: legacy?.description ?? null,
profile_image_url: legacy?.profile_image_url_https?.replace('_normal', '_200x200') ?? null,
followers_count: legacy?.followers_count ?? null,
verified: raw._raw?.core?.user_results?.result?.is_blue_verified ?? false,
}
}
function extractUrls(raw: RawBookmarkFull): UrlInsert[] {
const urls = raw._raw?.legacy?.entities?.urls ?? []
return urls.map(u => ({
bookmark_id: raw.id,
display_url: u.display_url,
expanded_url: u.expanded_url,
domain: new URL(u.expanded_url).hostname.replace('www.', ''),
}))
}
```
### Phase 3: Upsert to Supabase
```typescript
// src/ingest/load.ts
async function loadBookmarks(bookmarks: BookmarkInsert[], authors: AuthorInsert[], urls: UrlInsert[]) {
const supabase = createClient(SUPABASE_URL, SUPABASE_SERVICE_KEY)
// 1. Upsert authors (dedup by id)
await supabase.from('authors').upsert(authors, { onConflict: 'id' })
// 2. Upsert bookmarks (dedup by id)
await supabase.from('bookmarks').upsert(bookmarks, { onConflict: 'id' })
// 3. Insert URLs (delete existing first for updated bookmarks)
const bookmarkIds = bookmarks.map(b => b.id)
await supabase.from('bookmark_urls').delete().in('bookmark_id', bookmarkIds)
if (urls.length > 0) {
await supabase.from('bookmark_urls').insert(urls)
}
}
```
**Batching:** Process in batches of 100 bookmarks at a time to avoid Supabase payload limits.
---
## Enrichment Pipeline
### LLM Enrichment
For each unenriched bookmark, call OpenAI gpt-4.1-mini with a structured output prompt:
```typescript
// src/enrich/llm.ts
const ENRICHMENT_PROMPT = `You are analyzing a Twitter/X bookmark. Extract structured metadata.
Tweet text: {text}
Author: @{username} ({display_name})
URLs in tweet: {urls}
Respond with JSON:
{
"category": "tool|project|opinion|tutorial|news|thread|launch|resource|demo|hiring|funding|meme|other",
"tags": ["ai", "dev-tools", ...], // 1-5 lowercase tags
"products": [ // tools/products mentioned (0-3)
{ "name": "Product Name", "url": "https://...", "repo_url": "https://github.com/..." }
],
"summary": "1-2 sentence summary of what this bookmark is about",
"relevance_score": 3 // 1-5 (5 = highly relevant tool/project, 1 = noise/meme)
}`
interface EnrichmentResult {
category: BookmarkCategory
tags: string[]
products: { name: string; url?: string; repo_url?: string }[]
summary: string
relevance_score: number
}
```
### Embedding Generation
```typescript
// src/enrich/embed.ts
async function generateEmbedding(text: string): Promise<number[]> {
// Combine tweet text + summary for richer embedding
const input = `${text}\n\n${summary}`
const response = await openai.embeddings.create({
model: 'text-embedding-3-small',
input,
dimensions: 1536,
})
return response.data[0].embedding
}
```
### Enrichment Orchestration
```typescript
// src/enrich/index.ts
async function enrichBatch(batchSize = 50) {
// 1. Fetch unenriched bookmarks
const { data: bookmarks } = await supabase
.from('bookmarks')
.select('*, authors(*), bookmark_urls(*)')
.is('enriched_at', null)
.order('ingested_at', { ascending: false })
.limit(batchSize)
// 2. Batch LLM calls (parallel with concurrency limit of 10)
const results = await pMap(bookmarks, async (bookmark) => {
const enrichment = await enrichWithLLM(bookmark)
const embedding = await generateEmbedding(bookmark.text + '\n' + enrichment.summary)
return { bookmark, enrichment, embedding }
}, { concurrency: 10 })
// 3. Write results back to Supabase
for (const { bookmark, enrichment, embedding } of results) {
// Update bookmark
await supabase.from('bookmarks').update({
category: enrichment.category,
summary: enrichment.summary,
relevance_score: enrichment.relevance_score,
embedding,
enriched_at: new Date().toISOString(),
}).eq('id', bookmark.id)
// Upsert tags
for (const tagName of enrichment.tags) {
const slug = tagName.toLowerCase().replace(/\s+/g, '-')
const { data: tag } = await supabase
.from('tags')
.upsert({ name: tagName, slug, count: 0 }, { onConflict: 'slug' })
.select()
.single()
await supabase.from('bookmark_tags').upsert({
bookmark_id: bookmark.id,
tag_id: tag.id,
})
}
// Upsert products
for (const product of enrichment.products) {
const slug = product.name.toLowerCase().replace(/[^a-z0-9]+/g, '-')
const { data: prod } = await supabase
.from('products')
.upsert({
name: product.name,
slug,
url: product.url ?? null,
repo_url: product.repo_url ?? null,
count: 0,
}, { onConflict: 'slug' })
.select()
.single()
await supabase.from('bookmark_products').upsert({
bookmark_id: bookmark.id,
product_id: prod.id,
})
}
}
// 4. Refresh denormalized counts
await supabase.rpc('refresh_tag_counts')
await supabase.rpc('refresh_product_counts')
}
```
```sql
-- Count refresh functions
create or replace function refresh_tag_counts() returns void as $$
update tags set count = (
select count(*) from bookmark_tags where tag_id = tags.id
);
$$ language sql;
create or replace function refresh_product_counts() returns void as $$
update products set count = (
select count(*) from bookmark_products where product_id = products.id
);
$$ language sql;
```
### Cost Estimate
- ~5,000 bookmarks estimated
- gpt-4.1-mini: ~400 tokens input + 200 output per bookmark = ~$0.30 total
- text-embedding-3-small: ~200 tokens per bookmark = ~$0.01 total
- **Total enrichment cost: ~$0.50** for full backfill
---
## API Design
The web UI queries Supabase directly via the client SDK (anon key + RLS). No custom API server needed.
### Client-side Queries
```typescript
// Search bookmarks
const { data } = await supabase.rpc('search_bookmarks', {
query: 'AI coding assistant',
category_filter: 'tool',
tag_slugs: ['ai', 'dev-tools'],
sort_by: 'relevance',
page_size: 20,
page_offset: 0,
})
// Semantic search
const embedding = await getEmbedding(query)
const { data } = await supabase.rpc('semantic_search_bookmarks', {
query_embedding: embedding,
match_threshold: 0.7,
match_count: 20,
})
// Get stats
const { data } = await supabase.rpc('get_bookmark_stats')
// Browse by tag
const { data } = await supabase
.from('tags')
.select('*, bookmark_tags(bookmark_id)')
.order('count', { ascending: false })
.limit(50)
// Browse by category
const { data } = await supabase
.from('bookmarks')
.select('*, authors(*)')
.eq('category', 'tool')
.order('relevance_score', { ascending: false })
.range(0, 19)
```
### Edge Function (for semantic search embedding)
```typescript
// supabase/functions/search/index.ts
// Needed because we can't expose OpenAI key to the client for embedding generation
Deno.serve(async (req) => {
const { query, mode } = await req.json()
if (mode === 'semantic') {
const embedding = await openai.embeddings.create({
model: 'text-embedding-3-small',
input: query,
})
const { data } = await supabase.rpc('semantic_search_bookmarks', {
query_embedding: embedding.data[0].embedding,
})
return new Response(JSON.stringify(data))
}
// Fallback to full-text
const { data } = await supabase.rpc('search_bookmarks', { query })
return new Response(JSON.stringify(data))
})
```
---
## Web UI
### Pages
| Route | Description |
|-------|-------------|
| `/` | Home — search bar, featured/recent bookmarks, stats |
| `/search?q=...&category=...&tags=...` | Search results page |
| `/categories/[slug]` | Browse by category |
| `/tags/[slug]` | Browse by tag |
| `/authors/[username]` | Bookmarks from specific author |
| `/products/[slug]` | Product page — all bookmarks mentioning it |
| `/stats` | Dashboard — counts, top tags, top authors, timeline |
### UI Wireframe (Text)
```
┌─────────────────────────────────────────────────────────────┐
│ 🔖 Ben's Bookmarks [Stats] │
│ │
│ ┌─────────────────────────────────────────────────────┐ │
│ │ 🔍 Search bookmarks... [Search] │ │
│ └─────────────────────────────────────────────────────┘ │
│ │
│ [AI] [Dev Tools] [Launch] [Project] [Tutorial] [News] │
│ │
│ 5,234 bookmarks indexed • 892 tools • 342 authors │
│ │
│ ─── Recent ────────────────────────────────────────────── │
│ │
│ ┌─────────────────────────────────────────────────────┐ │
│ │ 🏷️ Tool ⭐ 5/5 │ │
│ │ │ │
│ │ @username · Mar 19 │ │
│ │ "Just launched ProductName — an AI coding │ │
│ │ assistant that..." │ │
│ │ │ │
│ │ [AI] [dev-tools] [coding] 🔗 View tweet → │ │
│ │ ProductName → │ │
│ └─────────────────────────────────────────────────────┘ │
│ │
│ ┌─────────────────────────────────────────────────────┐ │
│ │ 🏷️ Project ⭐ 4/5 │ │
│ │ │ │
│ │ @another_user · Mar 18 │ │
│ │ "Check out this open-source framework for..." │ │
│ │ │ │
│ │ [open-source] [framework] 🔗 View tweet → │ │
│ └─────────────────────────────────────────────────────┘ │
│ │
│ [Load more...] │
│ │
│ ─── Sidebar (desktop) ────────────────────────────────── │
│ │ Filter by: │
│ │ Category: [dropdown] │
│ │ Tags: [multi-select] │
│ │ Author: [search] │
│ │ Date: [range picker] │
│ │ Sort: [Relevance | Date | Likes] │
│ │ │
│ │ Top Tags: │
│ │ AI (423) · Dev Tools (312) · ... │
│ │ │
│ │ Top Products: │
│ │ Cursor (45) · v0 (38) · ... │
└─────────────────────────────────────────────────────────────┘
```
### Search Results Page
```
┌─────────────────────────────────────────────────────────────┐
│ 🔖 Ben's Bookmarks [Stats] │
│ │
│ ┌─────────────────────────────────────────────────────┐ │
│ │ 🔍 AI coding assistant [Search] │ │
│ └─────────────────────────────────────────────────────┘ │
│ │
│ 42 results for "AI coding assistant" │
│ Mode: [Full-text] [Semantic] Sort: [Relevance ▼] │
│ │
│ ┌── Filters (collapsible on mobile) ──────────────────┐ │
│ │ Category: [All ▼] Tags: [+ Add tag] │ │
│ │ Date: [Any time ▼] Author: [Any ▼] │ │
│ └─────────────────────────────────────────────────────┘ │
│ │
│ [Result cards...] │
│ │
│ ← 1 2 3 ... → │
└─────────────────────────────────────────────────────────────┘
```
### Design Notes
- **Color scheme:** Dark mode default, light mode toggle. Minimal — let the content breathe.
- **Card design:** Compact. Author avatar + handle. Category badge (colored). Tag pills. Faded engagement metrics.
- **Mobile:** Full-width cards. Filters collapse into a sheet/drawer. Search bar sticky at top.
- **Performance:** Static generation for browse pages. Client-side search. Debounced input. URL state for filters (shareable links).
- **Brand:** "Ben's Bookmarks" or "BenMarks". Subtle Ben's Bites branding if desired.
### Key Components
```
src/
├── app/
│ ├── page.tsx # Home
│ ├── search/page.tsx # Search results
│ ├── categories/[slug]/page.tsx
│ ├── tags/[slug]/page.tsx
│ ├── authors/[username]/page.tsx
│ ├── products/[slug]/page.tsx
│ └── stats/page.tsx
├── components/
│ ├── search-bar.tsx # Main search input
│ ├── bookmark-card.tsx # Result card
│ ├── filter-sidebar.tsx # Category/tag/author filters
│ ├── filter-drawer.tsx # Mobile filter drawer
│ ├── category-badge.tsx # Colored category pill
│ ├── tag-pill.tsx # Tag chip
│ ├── pagination.tsx
│ ├── stats-dashboard.tsx
│ └── theme-toggle.tsx
├── lib/
│ ├── supabase/
│ │ ├── client.ts # Browser client
│ │ ├── server.ts # Server client
│ │ └── types.ts # Generated types
│ ├── search.ts # Search helpers
│ └── utils.ts
└── hooks/
├── use-search.ts # Search state management
├── use-filters.ts # Filter state + URL sync
└── use-debounce.ts
```
---
## Sync Architecture
### Daily Sync
```
┌──────────────┐ ┌─────────────┐ ┌────────────┐ ┌────────────┐
│ Cron Trigger│────▶│ Pull new │────▶│ Transform │────▶│ Enrich new │
│ (daily 6am) │ │ bookmarks │ │ & upsert │ │ bookmarks │
└──────────────┘ └─────────────┘ └────────────┘ └────────────┘
```
**Strategy:**
1. Pull latest N bookmarks (e.g., 200) via `bird bookmarks --json-full -n 200`
2. Compare against existing IDs in Supabase
3. Insert only new ones
4. Run enrichment on unenriched bookmarks
5. Log sync stats to `sync_state` table
**Why not `--all` daily?** The bird CLI paginates through all bookmarks each time. For daily sync, we just need recent ones. The `--all` flag is for initial backfill only.
### Initial Backfill
```bash
# One-time: pull ALL bookmarks
bookmarks sync --all
# This runs:
# 1. bird bookmarks --json-full --all
# 2. Transform all
# 3. Bulk insert to Supabase
# 4. Enrich in batches of 50
```
### Cron Setup (Mac Mini via launchd)
```xml
<!-- ~/Library/LaunchAgents/com.ben.bookmarks-sync.plist -->
<plist version="1.0">
<dict>
<key>Label</key>
<string>com.ben.bookmarks-sync</string>
<key>ProgramArguments</key>
<array>
<string>/Users/mini/.bun/bin/bun</string>
<string>run</string>
<string>/Users/mini/workspace/bookmarks-db/src/cli.ts</string>
<string>sync</string>
</array>
<key>StartCalendarInterval</key>
<dict>
<key>Hour</key>
<integer>6</integer>
<key>Minute</key>
<integer>0</integer>
</dict>
<key>StandardOutPath</key>
<string>/tmp/bookmarks-sync.log</string>
<key>StandardErrorPath</key>
<string>/tmp/bookmarks-sync-error.log</string>
<key>EnvironmentVariables</key>
<dict>
<key>PATH</key>
<string>/Users/mini/.bun/bin:/usr/local/bin:/usr/bin:/bin</string>
</dict>
</dict>
</plist>
```
---
## CLI
```
bookmarks <command>
Commands:
sync [options] Pull new bookmarks and enrich
search <query> Search bookmarks from terminal
stats Show database stats
enrich [options] Run enrichment on unenriched bookmarks
backfill Pull ALL bookmarks (initial setup)
Options:
sync
--all Pull all bookmarks (not just recent)
--skip-enrich Pull only, don't enrich
--dry-run Show what would be synced
search <query>
--category <cat> Filter by category
--tag <tag> Filter by tag
--limit <n> Max results (default: 10)
--semantic Use semantic search instead of full-text
enrich
--batch-size <n> Bookmarks per batch (default: 50)
--force Re-enrich already enriched bookmarks
--ids <id,...> Enrich specific bookmark IDs
```
---
## Project Structure
```
bookmarks-db/
├── AGENTS.md
├── package.json
├── tsconfig.json
├── .env.local # Supabase + OpenAI keys
├── .env.example
├── spec/
│ ├── SPEC.md # This file
│ └── progress.md # Build progress tracker
├── supabase/
│ ├── migrations/
│ │ ├── 001_initial_schema.sql
│ │ └── 002_search_functions.sql
│ └── functions/
│ └── search/index.ts # Semantic search edge function
├── src/
│ ├── cli.ts # CLI entry point
│ ├── config.ts # Env vars, constants
│ ├── ingest/
│ │ ├── pull.ts # bird CLI wrapper
│ │ ├── transform.ts # Raw → DB transform
│ │ └── load.ts # Supabase upsert
│ ├── enrich/
│ │ ├── llm.ts # LLM enrichment
│ │ ├── embed.ts # Embedding generation
│ │ └── index.ts # Orchestration
│ ├── search/
│ │ └── index.ts # Search functions
│ └── types.ts # Shared types
├── web/ # Next.js app
│ ├── next.config.ts
│ ├── tailwind.config.ts
│ ├── app/
│ │ ├── layout.tsx
│ │ ├── page.tsx
│ │ ├── search/page.tsx
│ │ ├── categories/[slug]/page.tsx
│ │ ├── tags/[slug]/page.tsx
│ │ ├── authors/[username]/page.tsx
│ │ ├── products/[slug]/page.tsx
│ │ └── stats/page.tsx
│ ├── components/
│ │ ├── search-bar.tsx
│ │ ├── bookmark-card.tsx
│ │ ├── filter-sidebar.tsx
│ │ ├── filter-drawer.tsx
│ │ ├── category-badge.tsx
│ │ ├── tag-pill.tsx
│ │ ├── pagination.tsx
│ │ └── stats-dashboard.tsx
│ ├── lib/
│ │ ├── supabase/
│ │ │ ├── client.ts
│ │ │ ├── server.ts
│ │ │ └── types.ts
│ │ ├── search.ts
│ │ └── utils.ts
│ └── hooks/
│ ├── use-search.ts
│ ├── use-filters.ts
│ └── use-debounce.ts
└── tests/
├── ingest.test.ts
├── enrich.test.ts
└── search.test.ts
```
---
## Phased Build Plan
### Phase 1: Foundation (Day 1)
- [ ] Init project (Bun + TypeScript)
- [ ] Create Supabase project
- [ ] Run schema migrations
- [ ] Build ingestion pipeline (pull → transform → load)
- [ ] Run initial backfill of ALL bookmarks
- [ ] Verify data in Supabase dashboard
- **Exit criteria:** All bookmarks in Supabase with raw data
### Phase 2: Enrichment (Day 1-2)
- [ ] Build LLM enrichment pipeline
- [ ] Build embedding generation
- [ ] Run enrichment on all bookmarks (batched)
- [ ] Verify categories, tags, summaries look correct
- [ ] Spot-check 20 random bookmarks for quality
- **Exit criteria:** All bookmarks enriched with categories, tags, summaries, embeddings
### Phase 3: CLI (Day 2)
- [ ] Build CLI with `search`, `sync`, `stats`, `enrich`, `backfill` commands
- [ ] Test search (full-text + semantic)
- [ ] Test sync (incremental pull + enrich)
- **Exit criteria:** All CLI commands working
### Phase 4: Web UI (Day 2-3)
- [ ] Scaffold Next.js app with shadcn/ui
- [ ] Build home page with search bar + recent bookmarks
- [ ] Build bookmark card component
- [ ] Build search results page with full-text search
- [ ] Build filter sidebar (category, tags, author, date)
- [ ] Build category/tag/author browse pages
- [ ] Build stats dashboard
- [ ] Add semantic search toggle
- [ ] Mobile responsive pass
- [ ] Dark/light mode
- **Exit criteria:** Full UI working locally
### Phase 5: Deploy & Polish (Day 3)
- [ ] Deploy to Vercel
- [ ] Deploy Supabase edge function for semantic search
- [ ] Set up custom domain
- [ ] Set up daily sync cron (launchd on Mac Mini)
- [ ] Add to services.yml + watchdog
- [ ] Performance audit (Lighthouse)
- [ ] SEO basics (meta tags, OG images)
- **Exit criteria:** Live site, daily sync running
### Phase 6: Stretch Goals
- [ ] "Similar bookmarks" on each card (vector similarity)
- [ ] RSS feed of new bookmarks
- [ ] Email digest (weekly top bookmarks)
- [ ] Bookmark collections/lists
- [ ] API endpoint for external consumers
- [ ] Chrome extension to add bookmarks directly
- [ ] Integration with Ben's Bites newsletter pipeline
---
## Environment Variables
```env
# Supabase
NEXT_PUBLIC_SUPABASE_URL=https://xxx.supabase.co
NEXT_PUBLIC_SUPABASE_ANON_KEY=eyJ...
SUPABASE_SERVICE_ROLE_KEY=eyJ...
# OpenAI (for enrichment + embeddings)
OPENAI_API_KEY=sk-...
# Twitter (bird CLI reads from ~/.secrets)
# AUTH_TOKEN and CT0 already configured
# App
NEXT_PUBLIC_SITE_URL=https://bookmarks.bentossell.com
```
---
## Open Questions
1. **Domain:** `bookmarks.bentossell.com` vs `bookmarks.bensbites.com` vs something else?
2. **Public vs gated:** Fully public, or require email signup for full access? (Recommend: fully public, great for SEO + brand)
3. **Bookmark folders:** The bird CLI supports `--folder-id`. Does Ben use bookmark folders/collections? Could map to UI categories.
4. **Thread expansion:** Should we pull full threads for bookmarked tweets that are part of threads? (More content but more complexity)
5. **Update frequency:** Daily sync at 6am — sufficient, or more frequent?
6. **Content moderation:** Any bookmarks that shouldn't be public? Need a "hidden" flag?Before building anything, I had two more agents read it. Codex first (My setup):
review the spec - suggest any improvements/missing pieces from it.
It found real gaps. And it added things: a way to hide bookmarks, a table logging every sync, locks so two syncs can’t run at once. Then I opened pi with Claude Opus, told it who’d done the last pass, and asked it to look the other way:
review the spec. suggest improvements. gpt 5.4 did the last pass. look for
overengineering and other issues
spec/SPEC.md
## Tables
authorsbookmarkstagsbookmark_tagsproductsbookmark_productsbookmark_urlssync_statesync_runs
## Pages
/Home: search bar, featured/recent bookmarks, stats/searchSearch results page/categories/[slug]Browse by category/tags/[slug]Browse by tag/authors/[username]Bookmarks from specific author/products/[slug]Product page: all bookmarks mentioning it/statsDashboard: counts, top tags, top authors, timeline
## Also
semantic search + embeddingsedge functionis_public / hidden_reasonrelevance_scoresync leasesfull-text searchretry when OpenAI says slow down
9 tables, 7 pages.5 tables, 3 pages.
Its verdict was that the spec read like it was for a team shipping a product, not one person shipping a personal tool. Ask an agent for improvements and you get more stuff. I wanted less. So: edit the spec with that, then implement the spec.
First version
It built the lot. It found my Supabase key, made a database there, pulled in 2,257 bookmarks, had a model write a summary and tags for every one, and put it live on Vercel.
That was the first version. It worked, but I didn’t like the look of it:
site looks like shit
It had another go on its own:
benmarks.vercel.app
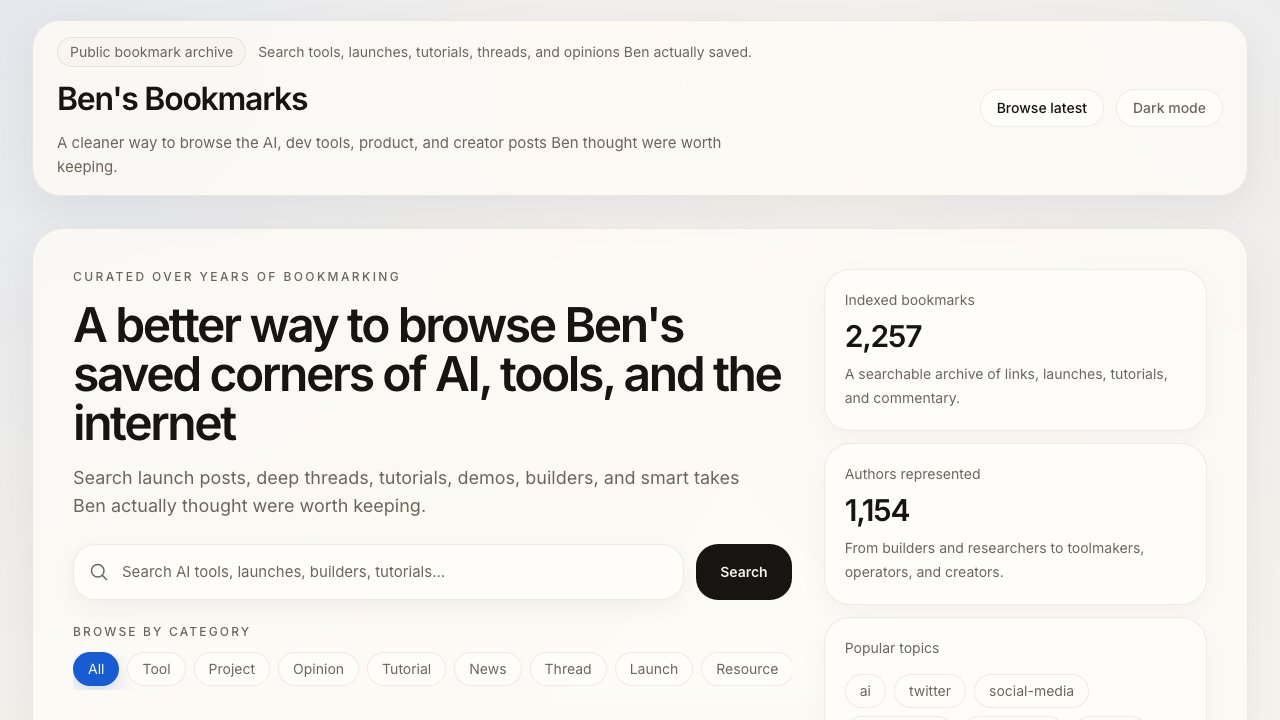
A headline, stats, “Public bookmark archive”. That’s a page for other people. I just wanted to find things. So I asked it to redesign it:
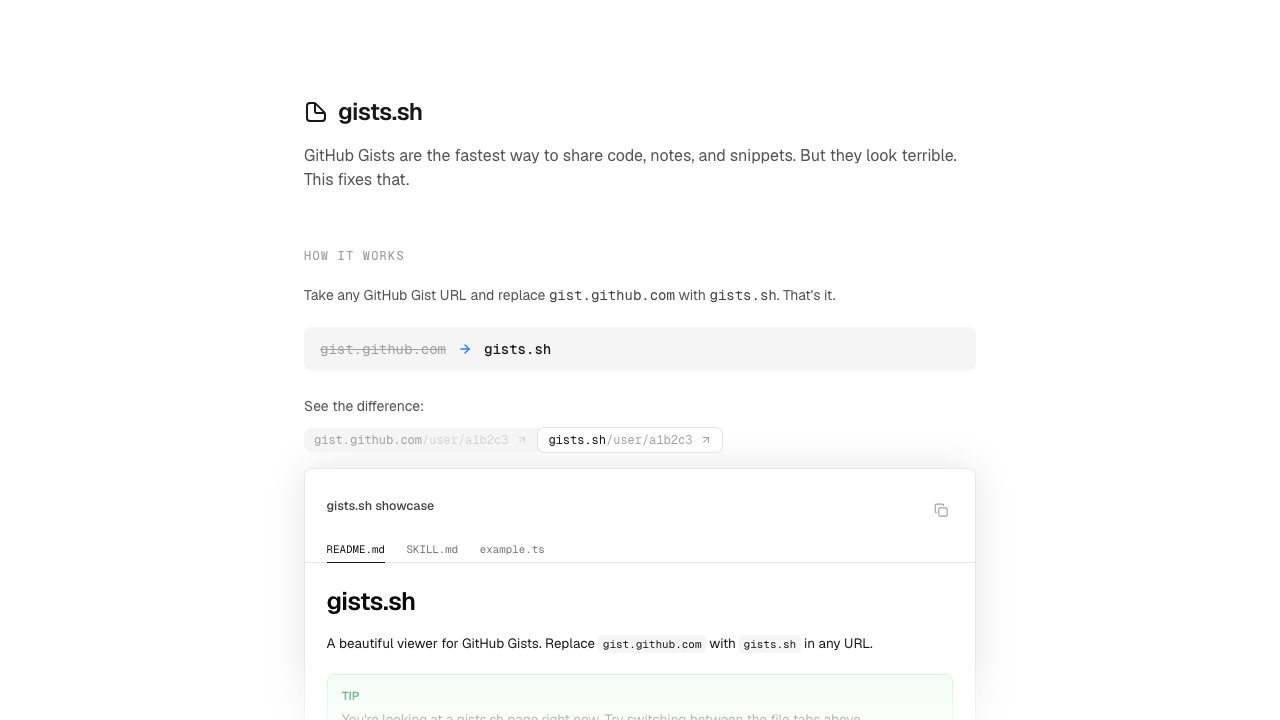
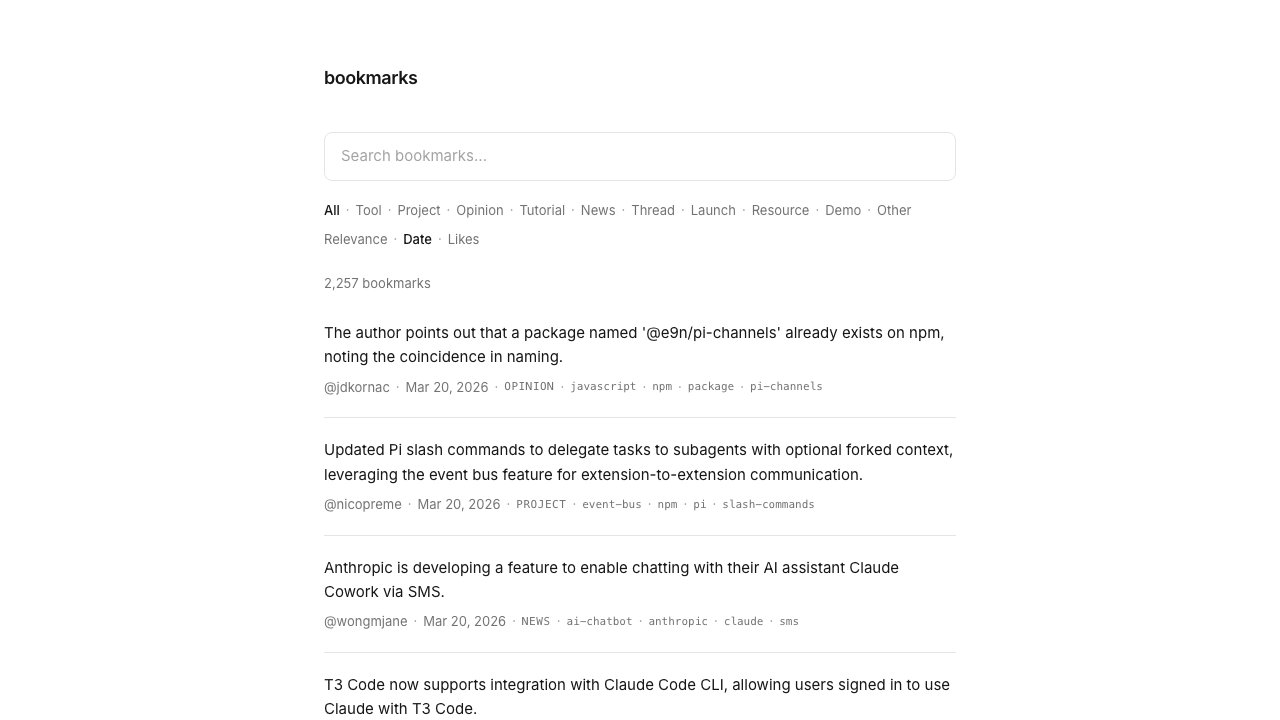
redesign this site. make it look like https://gists.sh - just need a way to search and filter my bookmarks. tweets dont need to be cards. its not for other people just a simple tool that looks beautiful that i can use to easily search my bookmarks
gists.sh is Fabrizio Rinaldi’s. It makes GitHub gists look good, and it’s plain in the way I wanted: one column, text, nothing else. Pointing at a site I liked got me there in one go. Then a couple of small rounds: a dark mode switch, and search that filters as I type.
Show me
It worked, and I had no idea how. What actually happens between me saving a post and it turning up here?
use visualise skill to show me how the pipeline works - when i bookmark a tweet, what happens for it to show up on the site
The visualise skill drew it instead of writing it out (Visualising). And once it was drawn, I could see what was wrong with it:
ok so some issues...
gpt 4.1 mini?! that model is fucking OLD should be using gpt-5.4-nano
shouldn't it just be as i save a tweet it gets pushed to the feed - i saw my recent ones did? rather than daily cron.
And there was no daily job. It was in the spec, so it was in the drawing, but nobody had set it up. X doesn’t tell anyone when you save a post, so the nearest thing to “as I save it” is checking often. It set up a job on my laptop to check every 15 minutes. Which made me think:
what happens when my laptop is off? - we need to put this repo and the launchd job on the mac-mini
So it copied the project to the Mini, started the job there, and took it off my laptop. My laptop sleeps. The Mini doesn’t.
What files are these in?
The categories were off. A third of everything was “opinion”. I could say it was wrong, but I couldn’t say what to change until I knew what I’d be changing:
what files are these in? is it a prompt the model then uses? i need to know what we're working with so i know what to tell yoiu to tweak
The project is a handful of files, and the categories come from one prompt in one of them:
Ten categories, not a word on what any of them meant, and no idea why I save anything. So I told it why:
so categories should be only;
- tools (github repos, skills, demos, products, product launches, etc)
- workflow (a tutorial/workflow/guide - something that i may be looking at to copy/adapt for my own workflows)
- media (podcasts, blog posts, etc
- other (anything that doesnt fit)
tags im fine with atm
Then it ran every bookmark back through the model with the new prompt.
Spot checks
While that ran, I went through the site checking what it had written. I spotted one:
ok this one has an incorrect description AND category
Bookmark referencing Hopper, a travel app, shared by Oskar Groth.↗
@oskargroth · Mar 20, 2026 · other · hopperapp
The post was a reply to me with a link and nothing else, so the model guessed from the web address. There’s a trick for that:
yeh so for links like that theres a trick, if you put https://markdown.new/[website-url] then the site should show as markdown which is easier to ingest for summarise
bookmarks-db.vercel.app
Hopper is a fast, native macOS disassembler and decompiler for reverse engineering, featuring CFG visualization, debugger support, and Python scripting via an integrated MCP server. ↗
Markdown is what models read best, and markdown.new turns a web page into it. Hopper is a Mac disassembler, not a travel app. Then a post about TelePi, a GitHub project, came out as Raspberry Pi. It’s a remote control for pi, the agent. So:
this trick should probably be used for every url tbh
Now every link in every post gets read before the model writes anything.
For my agents
I wanted my agents to be able to search it too.
cool. turn this product into a cli so my agents can search my bookmarks mega easily too - or is that redundant because they can use bird cli?
It wasn’t redundant. bird can pull my latest bookmarks, but it can’t search them, and it doesn’t have the summaries or tags. So now there’s a bookmarks command any agent on my machine can run, and one line about it in the instructions every agent reads (Setting up your agent):
Twice a week I write the newsletter. With the draft open in the browser, I ask:
look through my bookmarks since thursday. what links are not mentioned in the draft in the browser that should/could be?
That was in the first spec, under stretch goals: “Integration with Ben’s Bites newsletter pipeline”.
The database
The council spend map has a database too, but it’s a file on the Mac Mini, and only the Mini uses it. It adds everything up, writes two files, and the page just loads them. That wouldn’t work here, because three things use my bookmarks at once, from three places. The Mac Mini puts new ones in every 15 minutes. The site searches them every time I type. My agents search them from my laptop.
So they live in a database on Supabase, which all three can reach (My setup). A database is a set of tables, and every bookmark is a row:
bookmarks
| who | summary |
|---|---|
| @theo | T3 Code now supports integration with Claude Code CLI, allowing users signed in to use Claude with T3 Code. |
| @oskargroth | Hopper is a fast, native macOS disassembler and decompiler for reverse engineering, featuring CFG visualization, debugger support, and Python scripting via an integrated MCP server. |
| @theo | T3 Connect is a minimal open-source tunnel layer that lets you remotely control T3 Code instances from the T3 Code web/desktop/mobile with a one-command setup. |
| @theo | T3 Code is released for iOS and Android, allowing remote control of Claude and Codex after running “npx t3 connect” and installing the app. |
| ⋯ | |
authors
| username | name |
|---|---|
| @theo | Theo - t3.gg |
| @oskargroth | Oskar Groth |
| ⋯ | |
tags
| name | bookmarks |
|---|---|
| claude | 222 |
| t3-code | 7 |
| reverse-engineering | 6 |
| hopper | 1 |
| ⋯ | |
Who posted it and the tags are kept in tables of their own, so @theo is written down once and every one of his posts points at him. When I search, it looks at the summary and tags first, then who posted it and the post itself. It’s quick because it keeps a list of every word and which rows it’s in, so it doesn’t read all 6,000 rows every time I type a letter.
How it works
Everything goes through the database. The Mac Mini writes new bookmarks in. The site and my agents read them out. The site’s key can only read, so nobody can change anything through it. And the model only runs when a new bookmark comes in. Searching doesn’t touch it.
Make it your own
Everyone has a pile like mine. Saved posts, screenshots, links you emailed yourself. The bit I’d copy is the start: get a plan written, have another agent cut it down, then build.
i save [x bookmarks / screenshots / links i email myself] and can never find them again. write a short spec for a simple page where i can search them all, with a one line summary and a few tags on each. then review your own spec and cut anything that's overengineering for one person using it. show me what you cut before you build anything.
Notes
- My agent wrote a spec. Codex added to it, Claude cut the overengineering, then build it.
- The first version looked like shit. Pointing at gists.sh got the look in one go.
- I had it draw the pipeline so I could see it. That’s how I found the old model and the job that didn’t exist.
- The job moved to the Mac Mini, because my laptop sleeps.
- I asked what files the categories were in, so I knew what to change, then cut them to four.
- Spot checks found wrong summaries, so every link goes through markdown.new now. Then a command so my agents can search it too.